Skip to content
Hochschule für Informatik FHNW P9 — Mars Rover Autonomy

FHNW · School of Engineering · Master’s thesis

P9 — Mars Rover Autonomy

Autonomous manipulation and workflow automation for the FHNW Mars Rover

A vision-language-action policy, and the workflow layer that commands it — on a rover that competes at the European Rover Challenge.

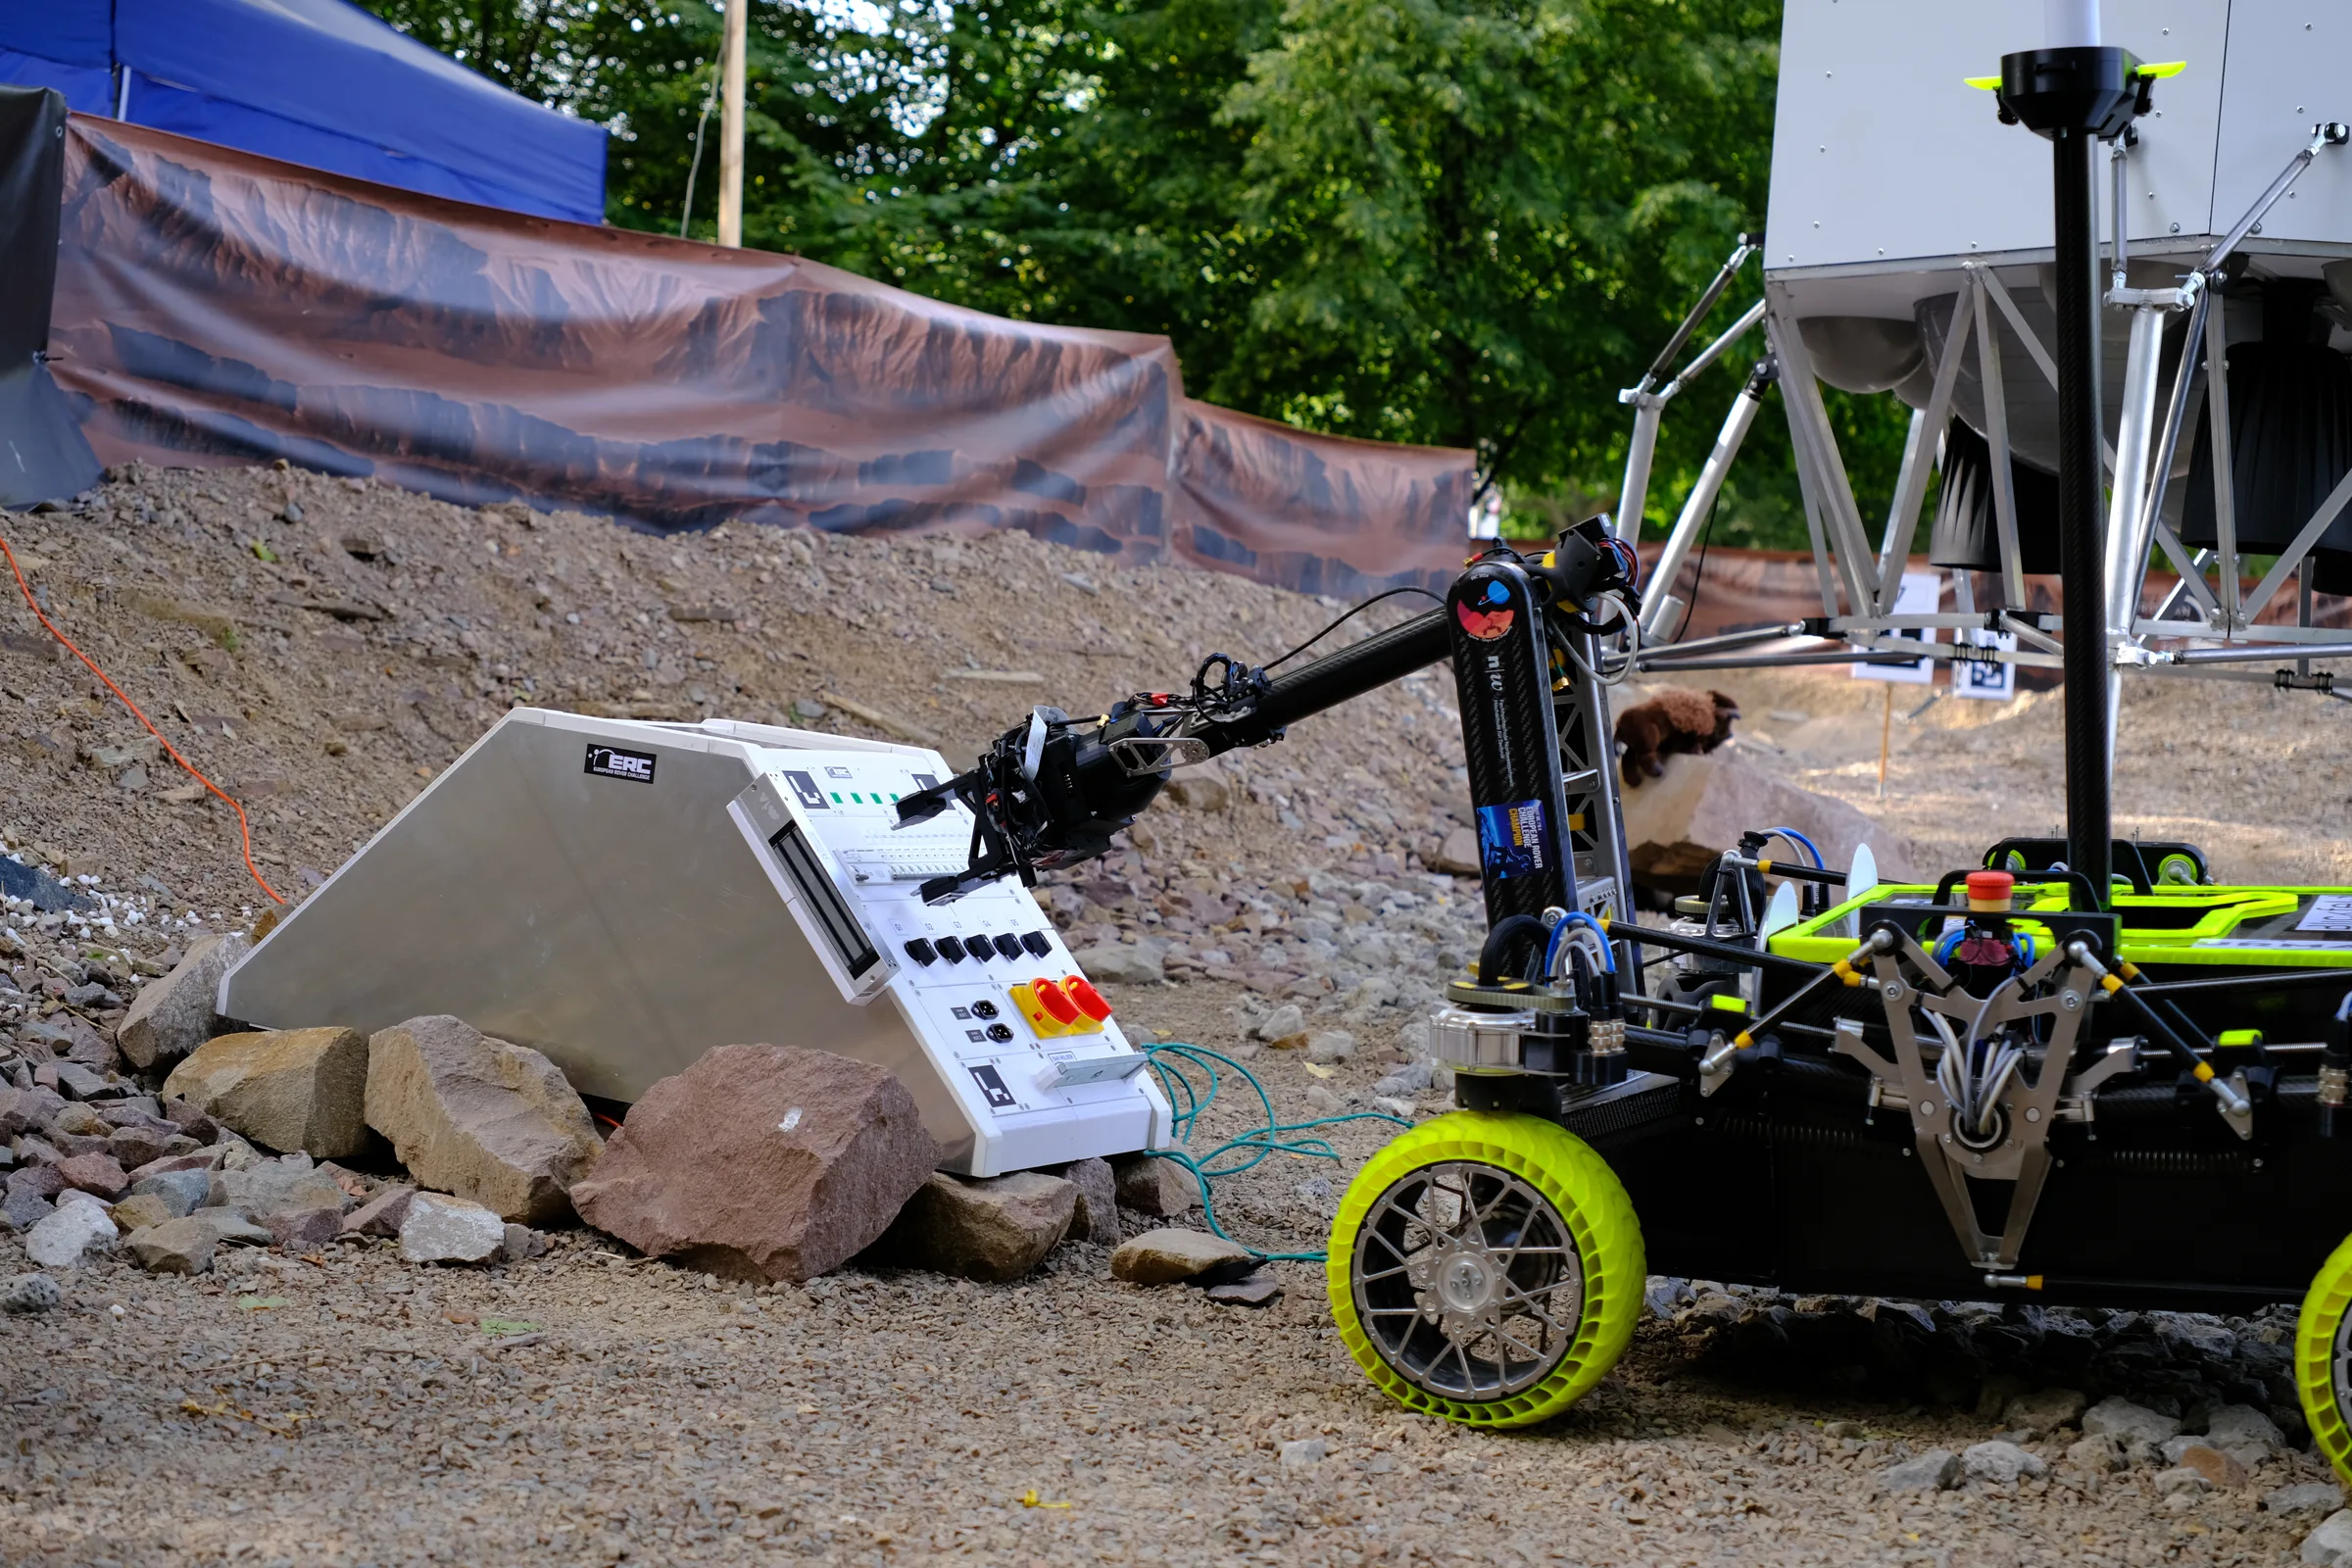
The FHNW Mars Rover with its six-degree-of-freedom manipulator

What this is

One manipulator, two ways to command it

The FHNW Rover Team competes in the European Rover Challenge, where one of the tasks is operating a maintenance panel. Building on a ROS 2 stack that already ran per-task imitation policies, this thesis rebuilds how that manipulator is commanded — a policy that takes an instruction, and a workflow layer that composes the sequences around it.

The report covers all of this in detail. This page is for the parts a PDF cannot hold: a rover you can send somewhere, workflows you can open, and a policy you can argue with.

What was built

Two systems

  1. 01

    SmolVLA, post-trained with RECAP

    A single SmolVLA policy conditioned on a natural-language task description replaces the per-task ACT models of the previous project, post-trained with RECAP, an advantage-conditioned reinforcement-learning recipe. It is re-tasked by changing the instruction rather than by loading another model.

    68.1 %

    average LIBERO success, from 62.9 %

    One full pass around the RECAP loop, rollout collection included.

    RQ1 · task automation and reinforcement learning

    Open the RECAP demo
  2. 02

    n8n workflows over ROS 2

    n8n is bridged to ROS 2 over rosbridge, giving operators a no-code way to compose task sequences from topics, services and actions, with the required order of operations enforced. An LLM agent built inside n8n answers free-text questions by calling those same tools, and a small fine-tuned model runs it on board at no per-call cost.

    93 %

    tool calls on 43 held-out prompts

    Against the cloud configuration’s 92 %: fine-tuning closed the gap, it did not overtake it.

    RQ1 · task automation, RQ3 · order enforcement and human-in-the-loop

    Open the n8n demo

Alongside them

  • Real-time deployment

    330 ms

    per chunk, ≈3 Hz replanning

    Compiled to TensorRT as a VLM prefix and an action expert at different precisions, which is what fits the policy into the control cycle on the Jetson Orin.

  • Depth sensing

    64 cells

    added to the state vector

    The gripper’s 8×8 time-of-flight grid enters the policy through one configuration entry. Whether the policy is better for it was not measured; the ablation is future work.

  • Visual servoing

    18.1 mm

    median error, 25 mm required

    A classical approach phase for targets language cannot name precisely — “the third switch from the left” — handing the policy a consistent starting pose.

The layer underneath

Manipulator control and safety gating

Described last in the report as the supporting work it is, rather than as a contribution of its own.

The six-degree-of-freedom manipulator is driven with FZI’s Cartesian controllers, extended here with a per-joint weighting that damps the forearm roll so it no longer absorbs wrist rotations, and mirrored by a MuJoCo model for smoke tests.

Both autonomous control modes are gated. A heartbeat from the operator station must be present, so a lost link halts autonomous motion without anyone having to act, and a latching software e-stop aborts the running policy or alignment goal and refuses new ones until it is reset.

The part a PDF cannot hold

Three things you can drive

Live · read-only

A virtual rover, driven by n8n

A simulated rover offering real ROS 2 topics, services and actions, driven by eleven n8n workflows — and a read-only live view anyone can open. Send it to the lake from your phone, watch the battery watchdog preempt a patrol, or ask the agent what interfaces the robot has.

  • Live view of the robot, read-only at the protocol level
  • All eleven workflows on a real n8n canvas
  • The n8n editor, the drive form, and the agent chat
Open the demo

Runs in your browser

SmolVLA + RECAP + guidance, client-side

The policy family from the first of the two systems, solving PushT entirely in the browser: Chipmunk2D physics as WASM, inference on WebGPU. Drag the agent away and watch the policy recover; move the guidance weight and watch what it does — and does not — change.

  • Take over from the policy mid-episode
  • Sampled action chunks drawn on the arena
  • Guidance weight and the denoising steps, both scrubable
Open the demo

On the Hugging Face Hub

Browse the demonstrations the policy learned from

Every episode the manipulator was taught, in LeRobot’s dataset viewer: camera streams, joint states and actions, scrubbable frame by frame. This is the raw material behind the policy — what a demonstration actually looks like, including the ones where the operator fumbled.

  • Camera and state streams, synchronised per frame
  • Episode by episode, no download required
  • Apache-2.0, alongside the other fhnwrover datasets
Open on Hugging Face

End to end, on the arm

What it actually does

The pipeline is demonstrated end to end on the manipulator. The deployed policy turns a rotary panel switch on roughly four attempts in five — below a teleoperating human, but repeatable until it succeeds. Lever switches, whose motion first tensions and then snaps over, are harder and carry fewer demonstrations.

Still open

Plug insertion is the one substep still open, and for a reason worth stating plainly: an operator cannot teleoperate it well enough to demonstrate it, so there is nothing to imitate. A purpose-built tool now exists but has not yet been used to record it.

LIBERO rollouts

What the policy learned, and what it did not

Evaluation episodes of the policies compared in the report. Filenames in the source encode policy, task, outcome and episode; these are three pairs where the difference is visible rather than statistical.

A skill only co-training recovers

GOAL suite — “open the middle drawer of the cabinet”

The skill is present in the expert demonstrations and absent from the base policy’s own rollouts. Rollout data sharpens behaviour a policy already shows; behaviour it lacks has to come back from the demonstrations, which is what co-training mixes in.

Base policy timeout The gripper hovers in front of the cabinet, never engages the handle, and the episode runs out.
Co-trained success The gripper reaches the handle and pulls the drawer open.

Where long horizons break down

LONG suite — one subgoal against two

The suite average is dragged down by instructions that chain two subgoals, because the error of each compounds. Single-subgoal tasks in the same suite reach 70–80 %.

One subgoal success “Pick up the book and place it in the back compartment of the caddy.” The policy completes it.
Two subgoals timeout “Put both the alphabet soup and the cream cheese box in the basket.” The first object is placed, the second is never picked up.

The two RECAP variants do not agree everywhere

SPATIAL suite — the same task, two post-training recipes

Co-training is not uniformly better. On this SPATIAL task the rollout-only policy succeeds where the co-trained one fails — a reminder that the suite averages in the report are averages, and that SPATIAL is the suite most sensitive to guidance.

Co-trained failure The same task the rollout-only policy completes.
Rollout-only success Reaches, grasps and transports the bowl.